Consistency models
Learn what consistency models guarantee, which model fits your data, and how to avoid the silent data corruption that happens when you choose wrong.
Introduction
Distributed systems may hold several versions of the same data at once. Consistency models make that behavior explicit: they define what readers may observe, how much coordination writes require, and which stale or conflicting results an application must handle. Mental model: replicas are copies that may temporarily disagree; the consistency contract defines which disagreement is allowed.
TL;DR
- A consistency model is a contract between a distributed system and its clients, defining what value a read is legally allowed to return after a write completes.
- There are five useful levels — linearizability, sequential, causal, session, and eventual — forming a spectrum from strong real-time ordering to convergence after writes stop.
- The core trade-off: stronger consistency often requires coordination or synchronous replication, adding latency that depends on topology and failure handling. Weaker models can be faster but may return stale data.
- Use the weakest model your correctness requirements allow. Social like counts tolerate eventual. Bank balances do not.
- The most dangerous consistency bug is silent: no exception fires, no error log appears — your system just silently serves wrong data to users.
The Problem It Solves
It's 9:14 a.m. on a Tuesday. A customer calls your payments support line, furious. She transferred $500 from checking to savings at 9:12 a.m., her bank app confirmed the transfer, and then she immediately tried to pay a bill — and got hit with an insufficient funds (NSF) fee. The $500 appeared in her savings account but the checking balance still showed the old pre-transfer amount.
Your database has three replicas: one in us-east-1, one in us-west-2, one in eu-west-1. The write went to the primary in us-east-1. The savings account replica in us-east-1 processed the write immediately.
But the checking balance lives on a different shard — and that shard's replica in us-west-2, where the bill payment read came from, hadn't received the update yet. The system served stale data. The transfer had committed according to one node; it hadn't propagated to the node that handled the next read.
This is a consistency failure. The system wrote correct data at the source then returned incorrect data on a subsequent read.
No code bug. No hardware failure. Just two nodes operating on different snapshots of reality.
The immediate instinct is: "this is a replication bug — fix replication lag." Replication lag is the mechanism, but the root design question is which stale reads the application permits.
The consistency model was undefined — and in a distributed system, undefined means anything goes. Define the consistency contract before writing the first line of replication code.
The silent danger of consistency failures
Consistency bugs produce no exceptions, no error codes, and no stack traces. Your metrics look healthy. Your error rate is zero. Users are just getting wrong data. This is why choosing a consistency model is a first-principles design decision, not an operational afterthought.
What It Is and Key Vocabulary
A consistency model is a formal contract that specifies which values are valid return results for a read operation given the history of write operations in the system. If a write commits value V for key K, the consistency model says: "which nodes, at which times, are allowed to return a value other than V for a subsequent read of K?" A useful framing is that the consistency model is what the storage layer guarantees to the reader — nothing more, nothing less.
The recurring vocabulary is: a replica holds a copy of the data; a stale read returns an older committed version; replication lag is the delay before a replica applies a write; a quorum is the set of replicas required for an operation; and conflict resolution decides what to do when concurrent writes diverge.
Analogy: Think of a shared Google Doc that three people have open simultaneously. When you type a new sentence:
- Linearizability is like a real-time collaborative document: after your sentence is committed, a later reader sees it, and all operations respect real-time order.
- Eventual consistency is like emailing a Word document around. You make a change, send it, and for a while people have old versions. Eventually everyone gets the update, but during that window, readers disagree on the current state.
- Causal consistency is like a thread on Slack: you can reply to a message, and everyone sees your reply after the message you're replying to — causal order is preserved — but two simultaneous messages from different people may appear in different orders to different people.
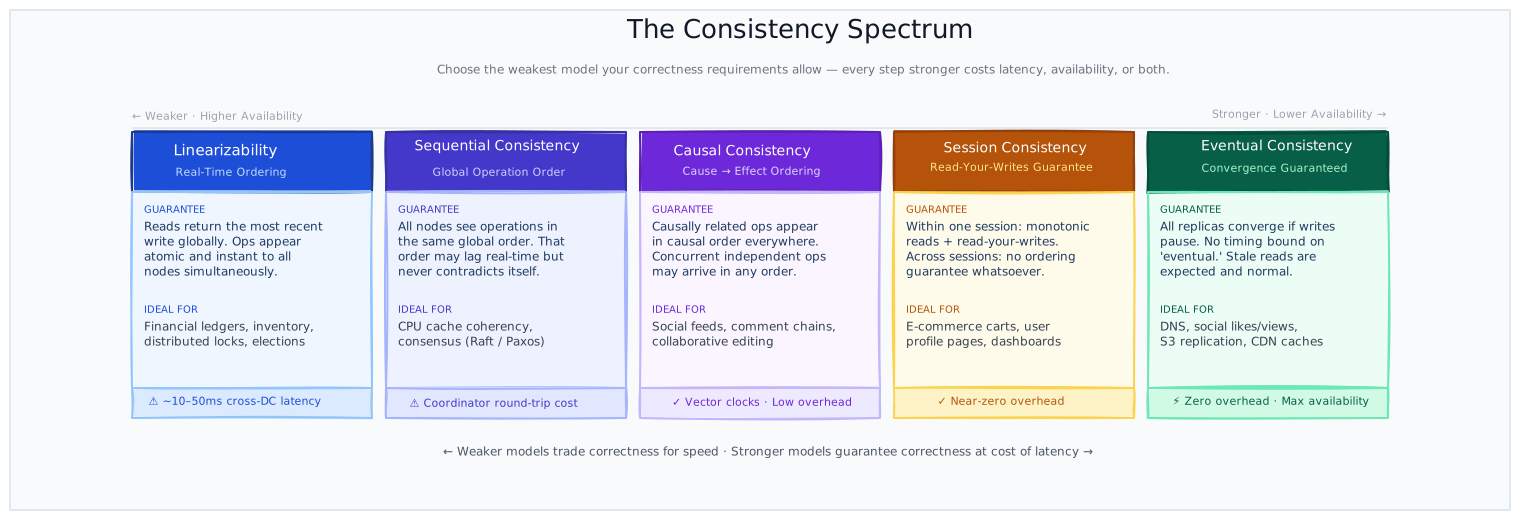
The right model is not always the strongest one. It's the weakest one your users will never notice.
How It Works
Every read in a distributed system returns a value from some version of the data. The consistency model determines which versions are legally returnable. In quorum-based systems, the useful rule to remember is W + R > N.
Consider a distributed key-value store with one primary and three replicas. When a write SET balance=500 arrives:
- The primary receives the write and appends it to its write-ahead log. The write is committed at this point — durable in the primary.
- Replication begins — the change propagates to replicas via WAL shipping or change streams. This takes time: 1–5ms same-rack, 10–30ms cross-DC, 100–500ms cross-region.
- Replicas apply the write when they receive it — each replica's view of the data advances independently.
- A read arrives — it hits a specific replica. The value it sees depends on which consistency model is enforced.
If the read and write quorums are formed from the same N replicas and versions are compared correctly, W + R > N guarantees that the sets overlap. That overlap is a quorum property; it is not, by itself, a complete proof of linearizability or serializable transactions.
// Quorum-based consistency — the core mechanism behind tunable models
// N = total replicas, W = write quorum, R = read quorum
// Quorum overlap: W + R > N ensures at least one overlapping node.
// The storage system still needs version-aware reads and appropriate
// failure/transaction semantics for a stronger end-to-end guarantee.

async function quorumRead(key: string, config: { R: number }): Promise<string> {
  // Fan the read out to all replicas simultaneously
  const reads = await Promise.allSettled(
    replicas.map(r => r.get(key))
  );

  const successful = reads
    .filter((r): r is PromiseFulfilledResult<{ value: string; version: number }> =>
      r.status === 'fulfilled'
    )
    .map(r => r.value);

  if (successful.length < config.R) {
    throw new Error(`Read quorum not met: got $\{successful.length\}, needed ${config.R}`);
  }

  // Pick the value with the highest version/timestamp among successful reads.
  // If W=2, R=2, N=3, the read and write sets overlap.
  return successful.reduce((latest, current) =>
    current.version > latest.version ? current : latest
  ).value;
}

// Cassandra-style consistency levels mapped to quorum formula:
// QUORUM: R = floor(N/2) + 1 — for N=3: floor(3/2)+1 = 2
// ONE:    R = 1              — eventual consistency, fastest, can return stale
// ALL:    R = N              — strongest possible, latency = slowest replica
const CONSISTENCY_LEVELS = {
  ONE:    { R: 1, W: 1 },   // N=3: 1+1=2 < 3 ? stale reads possible
  QUORUM: { R: 2, W: 2 },   // N=3: 2+2=4 > 3 ? quorum overlap
  ALL:    { R: 3, W: 3 },   // N=3: 3+3=6 > 3 ? highest quorum, blocks if any node is down
};
The quorum overlap rule
With N replicas, choose write quorum W and read quorum R so that W + R > N when the system's versioning and failure semantics support that guarantee. With N=3, W=R=2 gives quorum overlap and can tolerate one unavailable replica for an operation, subject to the store's availability rules.
Key Components
| Component | Role |
|---|---|
| Consistency level | The contract chosen per read or per write: ONE, QUORUM, ALL, LINEARIZABLE, etc. Most distributed stores let you choose per-operation. |
| Replication factor (N) | Total number of replica nodes that hold a copy. Higher N increases durability and read throughput, but increases write coordination cost. |
| Write quorum (W) | Number of replicas that must confirm a write before success is returned. W=1 is fastest; W=N blocks until all nodes confirm. |
| Read quorum (R) | Number of replicas consulted on a read. W+R>N achieves strong consistency; W+R=N allows stale reads. |
| Replication lag | Time delta between a commit on the primary and visibility on a replica. The direct driver of consistency failures under eventual models. |
| Vector clock | Per-node version counter attached to each write. Tracks causal relationships. Two writes are concurrent if their vector clocks are incomparable. |
| Session token / read-after-write cursor | A logical timestamp carried by the client that tells the replica "only serve this read if you've applied at least this version." |
| Conflict resolver | The function called when two concurrent writes create divergent replica state. LWW, MVCC, or CRDT-based. |
The Five Consistency Models
Linearizability (Strongest)
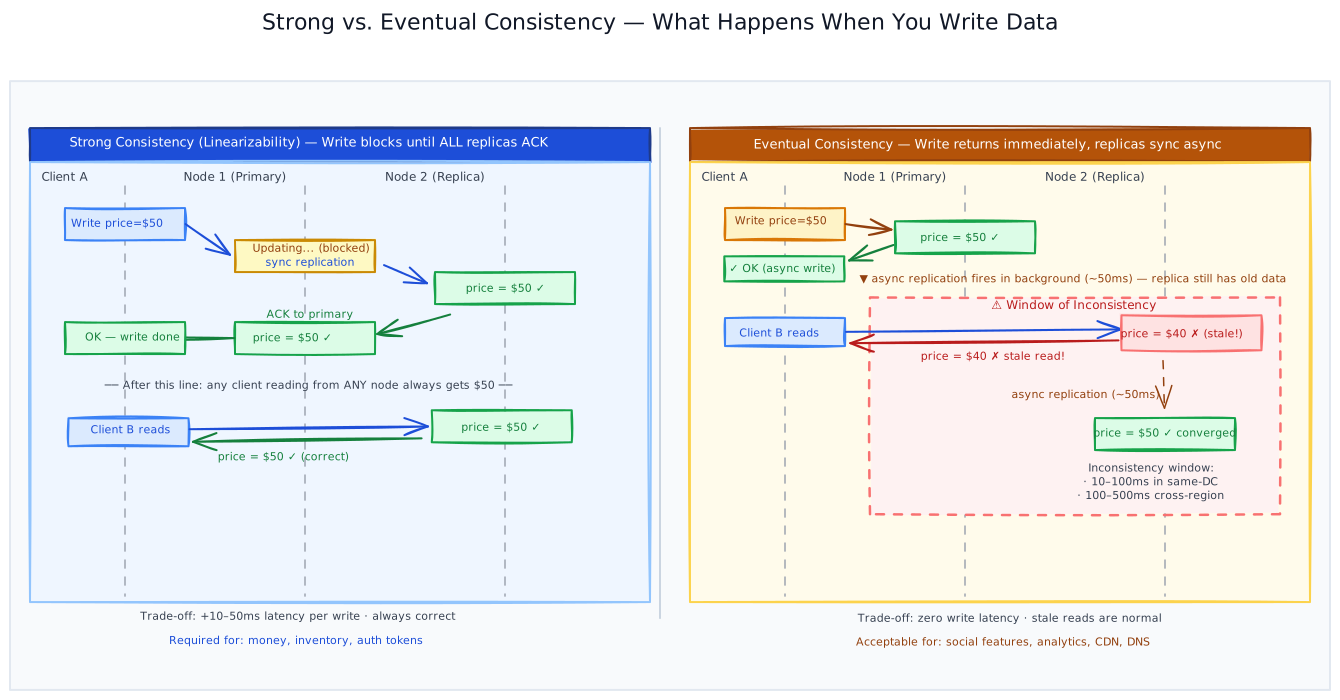
Linearizability is a strong real-time consistency model. It guarantees that every operation appears to execute atomically at a single point in time between its invocation and completion — meaning: if write W completes before read R begins, R must see W's value.
In plain terms: the system behaves as if there is one copy of the data, and every operation is instantaneous.
This is distinct from ACID's "C": ACID consistency usually means preserving declared schema and business invariants, while linearizability describes the real-time ordering visible to concurrent clients. A linearizable store does not expose a committed write as an earlier state to a later read, subject to the operation and availability semantics it provides.
How it's implemented: Common building blocks include synchronous replication before ACK, Raft consensus, and time-assistance techniques such as Spanner's TrueTime.
In a quorum-replicated implementation, a write waits for the required quorum confirmation before returning success to the client.
Cost: Every write adds a network round trip to cross-cluster confirmation. Same-DC: 10–20ms. Cross-region: 100–500ms.
Cross-region coordination is bounded by network round trips and processing time. The exact cost depends on placement, quorum rules, and whether the operation can be served locally.
When you need it: Distributed locks, leader election, financial account balances, inventory decrements, and other operations where concurrent actors acting on stale data could violate an invariant or cause material harm. The right choice still depends on the invariant, transaction scope, and failure behavior of the storage system.
Linearizability is the right choice when being wrong costs more than being slow.
Sequential Consistency
Sequential consistency relaxes the real-time requirement but preserves global ordering. All operations appear to execute in the same order to all observers, but that order doesn't need to match wall-clock time.
The key distinction from linearizability: Linearizability says if W finished before R started, R sees W. Sequential says all nodes see operations in the same order, but that order may not match real-world time. Operations might appear out of "real-time" order across different nodes, as long as the local programmatic order per process is respected.
In practice, Client A might see operations in order [W1, W2, R1] and Client B also sees [W1, W2, R1] — but W2 might have physically happened before W1 in wall-clock time. The ordering is consistent across clients, just not pinned to the clock.
Where it appears: CPU memory models (the Java Memory Model), consensus algorithms, and multi-primary databases that use a global sequence number. Harder to implement at global scale than linearizability (paradoxically) because you don't need real-time precision, but you still need global coordination.
In practice, sequential consistency is useful when all observers need one shared operation order but real-time ordering is not required. Many systems instead choose a stronger or more application-specific model.
Causal Consistency
Causal consistency is often a useful middle ground for distributed applications. It preserves the "cause-before-effect" relationship: if operation A causally precedes operation B, all nodes will see A before B. Concurrent, unrelated operations may appear in different orders on different nodes.
Two writes are causally related if:
- One write is a response to reading a value (you read the count, then increment it)
- A client performs them in the same session in order
- A
happens-beforerelationship exists in the system's vector clocks
Two writes are concurrent if neither causally precedes the other — two users independently updating different fields of a profile at the same moment.
How it's tracked: Vector clocks. Each node maintains a per-node counter vector. When a write is sent, the sender's vector is attached.
Receivers advance their own vector and use it to preserve causal order when serving or accepting dependent operations.
// Simplified vector clock — each node tracks its own + all other known operations
type VectorClock = Record<string, number>; // { "node1": 3, "node2": 1, "node3": 5 }

function happensBefore(a: VectorClock, b: VectorClock): boolean {
  // A happens-before B if all of A's counters are = B's counters
  // and at least one counter is strictly less
  const nodeIds = new Set([...Object.keys(a), ...Object.keys(b)]);
  let strictlyLess = false;

  for (const nodeId of nodeIds) {
    const aVal = a[nodeId] ?? 0;
    const bVal = b[nodeId] ?? 0;
    if (aVal > bVal) return false; // A can't happen-before B if any counter is greater
    if (aVal < bVal) strictlyLess = true;
  }

  return strictlyLess; // A ? B only if at least one counter is strictly less
}

function areConcurrent(a: VectorClock, b: VectorClock): boolean {
  // Concurrent = neither happens-before the other
  return !happensBefore(a, b) && !happensBefore(b, a);
}
Where it appears: Social threads and other systems with dependent writes often preserve causal order — if a comment depends on a post, readers should not see the comment before the post. Some databases expose causal or session guarantees through version and session metadata.
Causal consistency is easy to miss when the choice is described only as "strong" versus "eventual." It can handle many ordering requirements without imposing one global real-time order.
Session Consistency
Session consistency provides guarantees scoped to a single client session, rather than globally across all clients. Within a session, four sub-guarantees apply:
| Guarantee | Definition | Practical meaning |
|---|---|---|
| Read-Your-Writes | A client always sees its own writes | After you update your profile, you immediately see the update |
| Monotonic Reads | A client never sees a value older than one it already observed | If you see count=100, you'll never see count=95 on a later read |
| Monotonic Writes | A client's writes appear in the order they were issued | W1 is never visible without W2 if client wrote W1 then W2 |
| Writes Follow Reads | A write that follows a read will be at least as fresh as what was read | If you read V=5 then write V=10, no node can see V=10 before V=5 |
How it's implemented: Sticky routing (all reads for a session go to the same replica) or session tokens that encode the client's last-seen version (any replica with that version or newer can serve the read).
// Read-Your-Writes via session tokens — most production-safe implementation
interface SessionToken {
  lastWriteTimestamp: number;  // logical clock or hybrid logical clock
  sessionId: string;
}

async function readWithSessionConsistency(
  key: string,
  sessionToken: SessionToken
): Promise<{ value: string; newToken: SessionToken }> {
  // Find a replica that has applied at least up to lastWriteTimestamp
  // If no replica is caught up, wait up to 100ms then fall back to primary
  const replica = await findReplicaAtOrAfter(sessionToken.lastWriteTimestamp, {
    timeoutMs: 100,
    fallback: 'primary',
  });

  const result = await replica.get(key);

  return {
    value: result.value,
    // Advance the token: future reads need to be at least this fresh
    newToken: {
      sessionId: sessionToken.sessionId,
      lastWriteTimestamp: Math.max(sessionToken.lastWriteTimestamp, result.timestamp),
    },
  };
}
Where it appears: Cloud database SDKs commonly use session tokens or sticky connections to implement read-your-writes. Many eventually consistent systems provide at least this guarantee for user-facing flows because seeing your own update is often an important UX requirement.
That said, session consistency only protects your own writes — two different clients writing concurrently can still clobber each other with no warning.
Eventual Consistency (Weakest)
Eventual consistency makes one promise: if writes stop, all replicas will eventually converge to the same value. It makes no promise about when, and it explicitly allows stale reads during the convergence window.
BASE properties (contrast with ACID):
- Basically Available: The system always responds, even if the response might be stale
- Soft state: State can change over time due to propagation, even without new writes
- Eventually consistent: Given enough time without new writes, all replicas converge
The convergence window may be 10–100ms within a data center or 100–500ms cross-region in a healthy deployment, but there is no formal upper bound. Under write contention or an outage, the window can be indefinite.
The hard part isn't the model — it's conflict resolution. When two clients write to the same key concurrently across two different replicas, the system has two concurrent values. The merge decision determines whether the system silently loses data or surfaces conflict logic to API consumers. Three approaches:
| Strategy | How it works | When to use | Risk |
|---|---|---|---|
| Last-Write-Wins (LWW) | Each write carries a timestamp; highest timestamp wins | Simple, low-overhead | Clock skew causes silently lost writes |
| Multi-Version (MVCC) | Keep all concurrent versions; surface conflict to application | Shopping carts, collaborative edits | Application must implement merge logic |
| CRDTs | Use algebraic data types that merge automatically | Counters, sets, distributed flags | Limited to CRDT-safe data structures |
Last-Write-Wins can silently lose data
LWW is the default in Cassandra, Riak, and many other stores. It often uses the writing node's wall clock. If two nodes' clocks differ, writes can be silently overwritten by values that are newer according to one clock but older in real time. This is a production data-loss risk. If you use LWW, pair it with clock monitoring and a conflict policy that is appropriate for the data; a Hybrid Logical Clock can reduce, but does not eliminate, the risk.
Where it appears: Amazon DynamoDB (default), Apache Cassandra, Amazon S3, DNS, and any system that prioritizes availability over consistency (the A in CAP).
Eventual consistency is not a shortcut — it's a deliberate trade that you need to own end-to-end, from the write path through conflict resolution.
Conflict Resolution Strategies
Eventual consistency systems must handle the case where two writes with no causal relationship produce divergent replicas. This is unavoidable when writes are accepted at multiple nodes simultaneously.
Last-Write-Wins (LWW)
Every write carries a timestamp (usually the writing node's wall clock or a Hybrid Logical Clock). When two conflicting writes arrive at a replica, the one with the higher timestamp wins, and the other is silently dropped. A common post-incident discovery is that this policy was not understood until after data had already been lost.
Safeguard: Use Hybrid Logical Clocks (HLC) instead of pure wall clocks. HLC combines wall clock with a monotonic counter: HLC = max(wall_clock, last_seen_timestamp) + counter. This ensures monotonic advancement even when NTP causes clock drift, dramatically reducing silent data loss.
Multi-Version Concurrency Control (MVCC)
The database retains all concurrent versions of a value and surfaces the conflict to the application, which must implement a merge function. Amazon Dynamo uses this with "siblings" — concurrent writes produce multiple versions that the client merges on next read.
Classic example: A shopping cart. User A adds "Socks" on their phone. User B adds "Shirt" on their laptop.
Both writes go to different replicas. With MVCC, both items survive in the cart as separate versions that are merged to ["Socks", "Shirt"]. With LWW, one write is silently lost.
CRDTs (Conflict-free Replicated Data Types)
CRDTs are data structures with a mathematically proven merge operation that is commutative, associative, and idempotent — meaning any order of merging any subset of writes always produces the same result.
| CRDT type | Example | Real use |
|---|---|---|
| G-Counter | Increment-only counter | View counts, event totals |
| PN-Counter | Increment + decrement | Likes, votes |
| G-Set | Add-only set | Tracking unique visitors |
| OR-Set | Add and remove set | Tags, features flags |
| LWW-Register | Last-write-wins record | Single-field mutations (Note: lossy, drops concurrent edits) |
Redis, Riak, and collaborative editors use CRDTs. They move much of the merge logic into the data structure, but application-level choices about deletes, validation, and user-visible semantics still matter.
Failure Modes, Operational Concerns, and Trade-offs
Operationally, consistency failures are usually caused by an unbounded or unmeasured staleness window, an unsafe conflict policy, or a decision made from a replica that is not authoritative. Monitor replication lag, quorum errors, conflict counts, and the age of the data returned to clients.
| Pros | Cons |
|---|---|
| Weaker models (eventual, session) can avoid synchronous cross-replica coordination — reads and writes may return at the selected node's latency | Stronger models can add 10–500ms per write for cross-replica synchronization, depending on placement and protocol |
| Eventual consistency enables write availability during network partitions — the system keeps accepting writes even when replicas are separated | Eventual consistency produces stale reads — users can observe data that doesn't reflect the latest state, which is confusing or harmful in some contexts |
| Session consistency provides a useful UX guarantee (read-your-writes) with low coordination overhead — often implemented with a session token rather than full synchronization | Conflict resolution code is complex, error-prone, and usually untested until production — LWW silently loses writes, MVCC requires application-level merge logic |
| Causal consistency can preserve common dependent-write orderings with lower coordination than a global real-time order | Vector clock overhead grows with the number of nodes — at thousands of nodes, clock sizes become impractical without pruning strategies |
| Linearizability simplifies correctness reasoning because the system behaves like one logical node | A linearizable design may have to reject or delay operations without a quorum during a network partition, depending on its availability model |
The fundamental tension here is correctness vs. latency. Consistency is not free — every guarantee you add may require coordination between replicas, and coordination takes time across the network topology. Choose the model from the business invariant and its tolerated staleness, not from a generic preference for strong or weak consistency.
When to Use / When to Avoid
Every system that accepts writes can reach a point where two readers get different answers. The model chosen at design time determines whether that is an acceptable trade or a silent data-integrity bug.
Use linearizability when:
- The data represents a real-world resource with a hard limit: inventory units, financial balances, available seats.
- Concurrent actors on stale data produces an irrecoverable error: two processes both see lock-not-held and both acquire a distributed lock.
- You need distributed leader election or consensus: Raft and Paxos are built on linearizable operations.
- The business cost of wrong data exceeds the latency cost of synchronization.
Use causal consistency when:
- You have comment/reply chains, threaded discussions, or dependent writes where order matters causally but not globally.
- Same-DC latency is acceptable but global synchronization is not.
- You want stronger guarantees than eventual without paying the full linearizability tax.
Use session consistency when:
- Users write data and immediately read it back (profile updates, cart modifications, form submissions).
- You use read replicas for scale-out but can't tolerate "your own write is invisible to you."
- This is a common pragmatic default for user-facing web applications, when the application only needs per-session guarantees.
Use eventual consistency when:
- The data is aggregated or approximated by nature: view counts, recommendation rankings, search indexes.
- Writes happen at very high throughput and stale reads are acceptable (DNS TTL, CDN cache, social media feeds).
- You need maximum write availability and can tolerate brief inconsistency: you're refreshing a social feed and seeing a post from 2 seconds ago is acceptable.
- Business logic explicitly defers to conflict resolution: "last writer wins" for non-critical settings.
Avoid stronger-than-necessary consistency when:
- Writes are globally distributed: cross-region linearizability can add 100–500ms per write, which may be unacceptable for write-heavy workflows.
- The system must remain available during network partitions: linearizability requires coordination, which is impossible across a split network.
- Every millisecond of write latency is a user experience metric: e-commerce checkout, real-time gaming, high-frequency trading.
Match the model to the data's tolerance for wrongness — not to your engineering team's comfort level.
Session consistency is not the same as ACID transactions
ACID transactions guarantee consistency across multiple operations on multiple keys in a single atomic unit. Session consistency is scoped to a single client's reads and writes on potentially different nodes. Many applications mistake session consistency for a safety net against all consistency bugs — but a Read-Your-Writes guarantee says nothing about what two different clients see concurrently.
Real-World Examples
Google Spanner — Linearizability at Global Scale via TrueTime
Google Spanner is an example of a system that provides externally consistent reads and writes across data centers using a time API called TrueTime. In the original design, time-master infrastructure used GPS receivers and atomic clocks, and servers queried TT.now() to receive an interval [earliest, latest] bounded by uncertainty, typically around 1–7ms, rather than pretending that every machine had the same exact clock.
Before a write becomes externally visible, Spanner can wait until the latest time is definitively in the past. This commit-wait step complements, rather than replaces, the communication needed to coordinate replicated state. The result is strong external consistency with an additional commit-wait cost that depends on clock uncertainty; an uncertainty window of about 7ms, for example, implies roughly that much commit hold time.
Amazon Dynamo and DynamoDB — Eventual Consistency as a Design Principle
The original Dynamo (Amazon's internal key-value store, described in the 2007 paper) was designed explicitly for eventual consistency with tunable read/write quorums. The guiding insight: for Amazon's shopping cart, availability — the ability to add items even during regional outages — matters more than perfect consistency.
A customer seeing a cart with an extra item they did not add because of a merge conflict is a minor inconvenience. A customer unable to add items to a cart during an outage may abandon the purchase. This illustrates why a cart can sometimes favor availability, provided the conflict policy is explicit and the result is repairable.
Today, DynamoDB offers per-request strongly consistent reads (charged at 2x read capacity units) — but the default is still eventually consistent because at Amazon's scale, the latency difference matters economically.
Cassandra-style tunable consistency
Cassandra exposes consistency levels per operation: reads and writes can independently use ONE (fastest, may be stale), QUORUM (overlapping quorums when configured appropriately), LOCAL_QUORUM (quorum within a data center), or ALL (requires every replica to respond). These choices let a deployment favor local latency or broader coordination for different data types.
Choosing ALL makes every operation wait for the slowest required replica and reduces availability when any required node is down. Tunable consistency lets an operator choose different guarantees for different data types.
The pattern across all three: each system exposes stronger or weaker choices so the data can use a model it can tolerate, rather than applying the strongest model everywhere.
30-Second Explanation and 5-Minute Explanation
30-second explanation
A consistency model is the read contract for replicated data. Linearizability preserves real-time order, causal and session consistency preserve selected relationships or per-client progress, and eventual consistency lets replicas converge while allowing stale reads. Choose the weakest contract that still protects the business invariant, then pair it with an explicit conflict policy and a measurable staleness target.
5-minute explanation
Start with the invariant: what must never be wrong, and what staleness can the user tolerate? For a seat reservation or balance, enforce the decision at the authoritative owner with an atomic or serializable operation. For a feed or view count, asynchronous replication may be sufficient. If the store uses quorums, explain W + R > N as a set-overlap rule, then separately verify version ordering, transaction scope, and behavior when replicas or a quorum are unavailable. Finally, choose conflict resolution — LWW, MVCC, or a CRDT — and monitor lag, conflict rates, and read-after-write failures.
Practical questions
| Question | Concise answer |
|---|---|
| "How do you handle write conflicts in an eventual-consistency design?" | "Match the strategy to the data type. Use a CRDT for mergeable counters or sets, a Hybrid Logical Clock when last-writer-wins is acceptable, and MVCC when concurrent versions must survive for application-level merging." |
| "What consistency level fits a seat reservation?" | "Use an authoritative shard and an atomic compare-and-swap or serializable transaction so two buyers cannot both transition the seat from AVAILABLE to RESERVED. Measure the coordination latency against the checkout SLO." |
| "A Cassandra cluster has stale reads around a debit flow. What changes?" | "Do not treat a quorum read as a substitute for a multi-key transaction. Make the debit an atomic operation on an authoritative store, or use the database's transaction mechanism; use Cassandra for projections or audit reads when its guarantees fit." |
| "How do Spanner and CockroachDB differ in this context?" | "Both can provide strongly consistent distributed transactions, but they use different clock and consensus implementations and have different deployment and latency characteristics. Choose based on region placement, operational environment, transaction needs, and measured SLOs." |
| "When should an eventually consistent system move to a stronger model?" | "When stale or conflicting data can trigger a business event such as overselling, double payment, or an audit failure. Make that threshold explicit during design rather than waiting for a production incident." |
Common Mistakes and Misconceptions
- Treating replication lag as the consistency model. Lag is an operational signal; the model is the contract that says whether the observed staleness is allowed.
- Calling quorum overlap linearizability.
W + R > Nhelps a version-aware quorum read find overlap, but it does not automatically provide serializable transactions, real-time ordering, or safe behavior during every failure. - Using wall-clock LWW for important records. Clock skew can discard a valid concurrent update. Use a safer logical versioning scheme or preserve multiple versions when both writes matter.
- Using a replica read as a write precondition. Inventory, money, and other bounded resources need an atomic check-and-update at the authoritative owner.
- Confusing session consistency with ACID or CAP consistency. Read-your-writes improves one client's view; it does not coordinate two concurrent clients or preserve multi-key invariants.
Test Your Understanding
Q1. Your e-commerce site uses eventual consistency for inventory. You have 50 units of a viral item in stock. In a 200ms consistency window, you receive 500 requests all reading qty=50. All 500 proceed to checkout. How many orders succeed? How many fail? What specific mechanism determines the cutoff? And why does simply adding more replica nodes make this problem worse, not better?
Q2. Your team routes all reads to the primary database to implement "read-your-writes." At 10K requests/second, this works. At 100K requests/second, the primary is at 95% CPU. A junior engineer proposes: "Let's add 10 read replicas but keep read-your-writes by routing writes AND the reads immediately following writes to the primary, and all other reads to replicas." What specifically breaks under this design, and what is the production-safe implementation?
Q3. Two concurrent checkout flows read the same seat row (status='available') for seat A1 at a concert. Both decide "available — proceed." Both fire UPDATE seats SET status='sold' WHERE seat_id='A1'. Both receive success. Now seat A1 has been sold twice. What consistency model would prevent this? Why doesn't a regular BEGIN; SELECT ... FOR UPDATE solve this in a distributed database with sharded tables?
Q4. You're designing a food delivery platform. A driver's GPS position is updated every 3 seconds, and 100,000 customers might be viewing that driver's position simultaneously. Your architect says: "We need strong consistency — customers must see the latest position." Your CTO counters: "Eventual consistency with a 3-second staleness bound is fine — the driver position is only relevant every GPS update anyway." Who is right? What one number makes this an easy decision?
Q5. A startup's single-node MySQL provides effective linearizability. They add 5 read replicas for scale. An engineer confirms: "All reads still go to a specific replica per session — we have session consistency." Three months later, after a maintenance restart, one replica was accidentally configured without read_committed isolation. Users of that replica start seeing dirty reads — values written by transactions that haven't yet committed. What consistency model does that replica now provide, and why is it weaker than eventual consistency?
Q6. You have a distributed like counter: 1 billion posts, each receiving up to 10,000 like events/second during viral moments. You start with a linearizable counter on a single Redis node. At 500K likes/second globally, the Redis primary saturates. A colleague suggests: "Shard the counter into 100 Redis nodes — each shard holds 1/100th of the load." What specific consistency problem does sharding create for a single counter, and show two designs that preserve accuracy under this load at different consistency trade-offs.
Q7. Your platform uses eventual consistency for user profile data. A data scientist notices that 0.02% of user records have a null email field — but your signup form requires a non-null email. You've confirmed the bug isn't in application code. Upon investigation, you find that a schema migration 3 months ago added an email column without a database-level NOT NULL constraint. What consistency failure mechanism explains how records with null email exist, and how would you prevent this class of bug going forward?
Q8. Two competing architecture proposals: (A) Use CockroachDB (linearizable) for your entire data layer. (B) Use Cassandra (eventual) with application-level checks. Your system processes financial transactions AND social activity feeds. Under what specific conditions does (A) become worse than (B), and what hybrid architecture resolves the tension without double the operational complexity?
Quick Recap
- A consistency model is a contract that defines which values are legally returnable for a read, given the history of writes — it's not a configuration flag, it's a fundamental property of your system design.
- The spectrum runs from linearizability (every read returns the most recent write globally; operations appear atomic) down to eventual consistency (replicas converge when writes stop; stale reads are normal and expected).
- Session consistency (Read-Your-Writes + monotonic reads) covers many user-facing requirements with low coordination overhead — implement it with session tokens carrying write timestamps, not by routing every read to the primary.
- The W+R>N quorum formula gives tunable systems read/write-set overlap: with N=3 replicas, W=2 writes and R=2 reads overlap, while versioning and failure semantics determine the end-to-end guarantee.
- Last-Write-Wins is dangerous because wall clock skew can silently order writes incorrectly — always use Hybrid Logical Clocks (HLC) or version vectors instead of raw timestamps for conflict resolution.
- Linearizability kills cross-region write performance — a linearizable commit from Asia to a 3-region cluster adds 100–500ms of physics-limited latency; use it only for data where stale reads cause real business or audit harm.
- A good consistency decision names the model, the invariant it protects, the tolerated staleness, and the cost of the alternative — for example, compare-and-swap on the authoritative inventory write path instead of trusting a stale read.
Related Concepts
- Replication — Replication creates the replicas that make consistency a problem to solve. Async WAL shipping is the mechanism that produces replication lag, which is the physical cause of stale reads under eventual consistency.
- CAP Theorem — The theoretical framework for why you must choose between linearizability and availability during a network partition. Consistency models dictate how far you slide down from the "C" in CAP when optimizing for availability and partition tolerance.
- Databases — Your database engine determines which consistency levels are even possible. MVCC in Postgres, LWT in Cassandra, TrueTime in Spanner — the implementation sets your ceiling.
- Caching — Cache invalidation is a consistency problem in disguise. A cache entry is an eventually consistent replica of the DB — TTL and event-driven invalidation are consistency mechanisms, even if they're never called that.
- Sharding — Cross-shard transactions require distributed protocols (2PC, Saga) that compound consistency challenges. Sharding changes what consistency is physically achievable per-operation.
Related Articles
Master how database replication scales reads, survives failures, and trades off consistency for availability. Learn replica lag, read stale data purposefully, and why your most critical business logic must run on the primary.
Learn how databases organize data for fast retrieval, which storage engine to choose for your workload, and how ACID transactions keep concurrent writes correct at scale.
Learn why every distributed system must choose between consistency and availability when a partition strikes — and how to make that choice intentionally.
Learn how caching eliminates redundant database reads, which strategy to choose for your write pattern, and how to design a cache layer that survives invalidation at scale.