CAP Theorem
Learn why every distributed system must choose between consistency and availability when a partition strikes — and how to make that choice intentionally.
TL;DR
- CAP Theorem, in its usual distributed data-store model, says a system cannot guarantee strong Consistency, Availability, and Partition Tolerance together during a partition.
- In practice, partition tolerance is a design requirement for replicated systems: network partitions are possible. The real choice collapses to C (reject or delay rather than serve stale data) or A (return the local result and reconcile later).
- CP systems (HBase, ZooKeeper, etcd, Spanner) sacrifice availability during a partition — they return errors rather than serve potentially inconsistent data.
- AP systems (Cassandra, DynamoDB, CouchDB, Riak) sacrifice consistency during a partition — they return possibly stale data rather than fail requests.
- Consistency in CAP means linearizability in the usual model—reads respect the real-time order of completed writes—not ACID consistency. The CP-versus-AP decision is a useful way to describe partition behavior for replicated data.
The Problem It Solves
Imagine it is 11:42 PM on Cyber Monday. Your e-commerce platform runs in two data centers: US-East and EU-West. A routing or network failure interrupts the inter-datacenter link.
For 90 seconds, neither data center can reach the other. Both regions keep running independently.
A user in Frankfurt clicks "Place Order." EU-West has their cart data. But their loyalty reward balance — updated by a purchase 30 seconds earlier in the US — hasn't replicated yet.
The EU-West node holds an outdated balance.
Your system must now make a choice it may never have consciously designed for:
Option A: Refuse to process the checkout until connectivity restores. The user sees an error. You lose the sale. Your data is correct.
Option B: Process the checkout using the stale balance. The loyalty discount is wrong. You make the sale. Your data is wrong.
There is no third option that simultaneously gives both guarantees during this partition. Every distributed system picks one of these behaviors—whether the engineering team planned for it or not. The risk is discovering the default behavior during an incident instead of choosing it at design time.
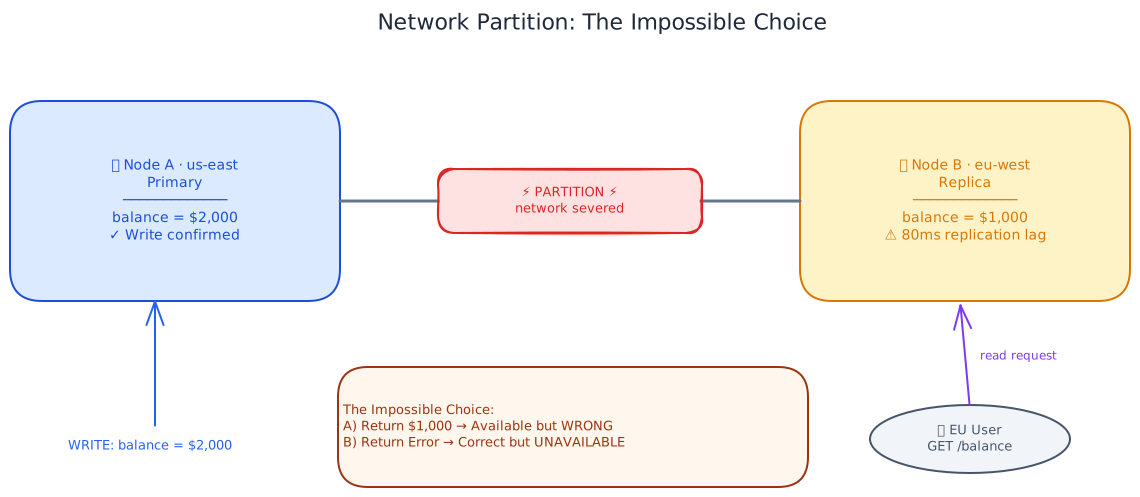
For every replicated data store you sketch, ask what it should do during a partition: refuse operations that cannot be confirmed, or continue with potentially stale state. That is the practical CAP decision—not an academic abstraction.
What Is It?
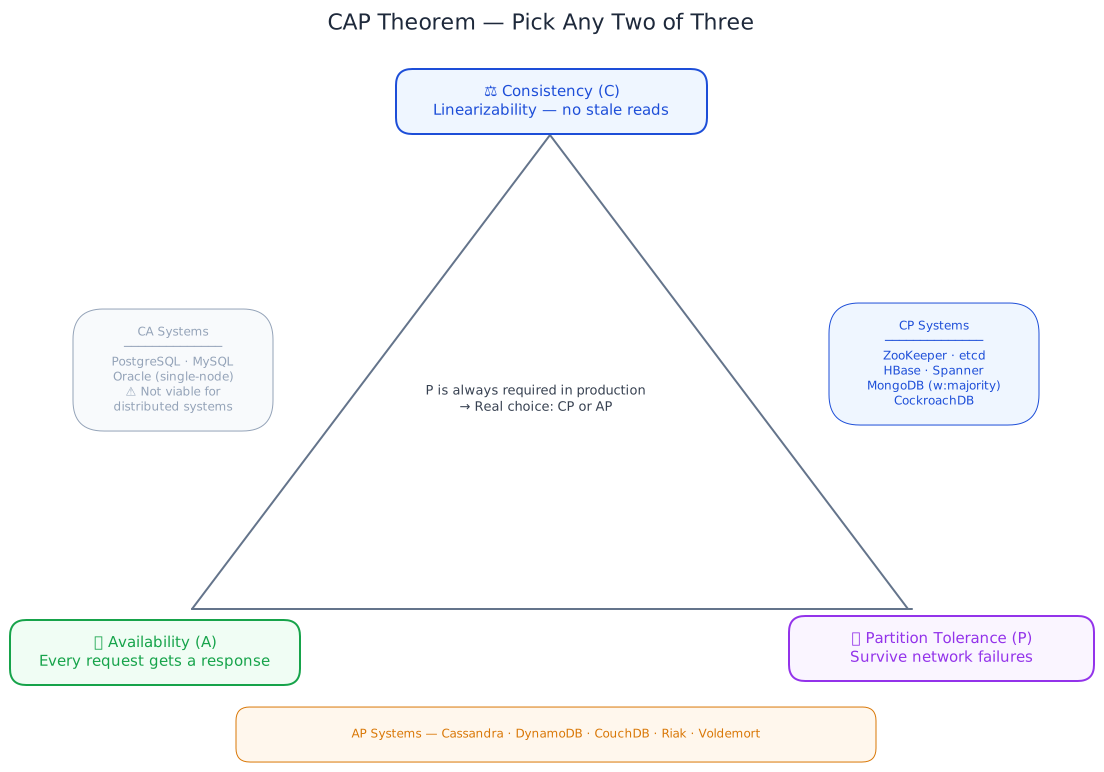
CAP Theorem, proposed by Eric Brewer in 2000 and formally proved by Gilbert and Lynch in 2002, states—in its usual distributed data-store model—that a system cannot guarantee both strong consistency and availability when a network partition is present. It is often summarized as choosing at most two of three properties:
-
Consistency (C): Every read respects the real-time order of completed operations and returns the latest value allowed by that order, or an error. In the common CAP framing this means linearizability. It is entirely different from the "C" in ACID (constraint preservation) and from eventual consistency.
-
Availability (A): Every request to a non-failed node gets a non-error response. The response need not be the most recent value. CAP Availability is a model-level guarantee, not an SLA percentage.
-
Partition Tolerance (P): The system continues operating even when network messages between nodes are lost, delayed, or reordered. The system does not require a perfectly reliable network to function.
Analogy: Think of two bank branches in different cities that share a central ledger via overnight courier. If the courier van breaks down (partition), each branch faces the same choice:
- Consistency: Neither branch processes any transactions until the courier van is repaired and the ledger is re-synced. Customers are turned away. The ledger is never wrong.
- Availability: Each branch keeps processing transactions from their last-known ledger copy. When the courier van is fixed, the branches reconcile. During the outage, some customers get incorrect balances.
The bank's choice depends on which outcome is worse: turning customers away, or occasionally showing wrong balances. Neither is zero-cost. Before selecting a data store, state which failure mode the system can tolerate and document that decision.
How It Works
The Proof: Why You Can't Have All Three
The proof is short and worth understanding once. It turns CAP from a slogan into a concrete consequence of a partition.
Imagine the simplest possible distributed system: two nodes, N1 and N2, both storing a variable x. Initially, x = 0 on both nodes.
Step 1: A client writes x = 1 to N1.
        N1 persists x = 1 locally.
        N1 tries to send the update to N2.
        But the network is partitioned — N2 never receives the write.

Step 2: Another client reads x from N2.

Now you must pick:
  If you want AVAILABILITY:
    N2 must respond. It returns x = 0.
    That is stale. Inconsistent. Wrong.

  If you want CONSISTENCY:
    N2 must return an error (or block until partition heals).
    It cannot return x = 1 — it hasn't received that write.
    So it cannot serve a response without violating consistency.

You cannot return x = 1 (correct) AND serve a response (available)
without N2 somehow knowing about the write — which requires
a working network. The network is broken. That's the partition.

Partition Tolerance means the system works despite this.
Given P is required, C and A cannot co-exist.
That is the complete proof. The partition is the forcing function. P is not optional in any real system running across multiple nodes, so the choice reduces to: sacrifice C or sacrifice A during a partition.
// Simplified: the binary branch every distributed system implements
async function read(key: string): Promise<Value | PartitionError> {
  const localValue = await localDb.get(key);
  const partitionDetected = !(await canReachQuorum());

  if (partitionDetected) {
    // CP BRANCH: sacrifice availability to guarantee correctness
    if (systemMode === "CP") {
      throw new PartitionError(
        "Quorum unreachable — cannot confirm data freshness"
      );
    }

    // AP BRANCH: sacrifice consistency to guarantee a response
    if (systemMode === "AP") {
      return {
        value: localValue,
        stale: true,
        lagMs: estimatedReplicationLag(),
      };
    }
  }

  // Normal path: no partition — quorum read guarantees strong consistency
  return await quorumRead(key);
}
The TypeScript above is a mental model, not a complete implementation. The C-or-A branch is the design decision to name explicitly for requests that arrive during a partition.
Key Components
| Property | CAP Definition | Common Misunderstanding | Concrete Example |
|---|---|---|---|
| Consistency (C) | Every read respects the real-time order of completed operations and returns the latest value allowed by that order, or an error. Formally: linearizability. | Confused with ACID consistency (schema constraints, referential integrity). These are different properties. | After a confirmed write of balance = $200, a later linearizable read cannot return the previous $150, regardless of which replica serves it. |
| Availability (A) | Every request to a non-failed node returns a non-error response. This is a model-level guarantee, not a 99.9% uptime target. | Confused with high-availability SLAs. CAP Availability concerns the behavior of each request in the model, not most requests over a time window. | During a partition, an AP-style system continues responding from reachable nodes even when it cannot confirm the freshest value. |
| Partition Tolerance (P) | The system continues to operate despite network partitions: messages lost, delayed, or nodes unreachable. | Assuming a reliable network makes partitions impossible. Routing, switch, host, and maintenance failures can still isolate replicas. | US-East and EU-West lose inter-datacenter connectivity while each region remains healthy internally. |
| Network Partition | A subset of nodes cannot communicate with another subset. Nodes are alive and running — the link between them is broken. | Confused with a total system outage (all nodes down). In a partition, nodes are healthy; only communication between them fails. | A top-of-rack switch failure splits a 6-node cluster into two groups of 3 that can't reach each other. |
| Quorum | A majority of nodes (⌊N/2⌋ + 1) used by many replicated protocols before a read or write is confirmed. The exact read/write rule is system-specific. | "Use quorum everywhere to be safe." Quorum writes can be slower and reduce write availability — apply them where correctness outweighs latency. | 5-node cluster, quorum = 3 (⌊5/2⌋ + 1 = 2 + 1 = 3). A majority quorum prevents two disjoint partitions from both committing under the protocol's assumptions. |
| Eventual Consistency | A weaker model in which replicas may temporarily diverge but are expected to converge when updates stop and repair succeeds. It is common in AP-oriented systems but is not synonymous with AP. | Equivalent to "no consistency at all." Not true—eventual consistency can define convergence rules (LWW, CRDTs) while weakening ordering guarantees. | Two nodes write different values to the same key during a partition. When the partition heals, a deterministic conflict rule resolves which value survives. |
| Linearizability | The "C" in CAP. Each operation appears to take effect atomically at a point between its invocation and response, respecting real-time order. | "Linearizability is just another name for transactional consistency." No — ACID and isolation describe different properties; a transactional database may still expose weaker read semantics. | After a confirmed write of balance = $200, a later linearizable read cannot return the previous $150, regardless of which replica serves it. |
Types / Variations
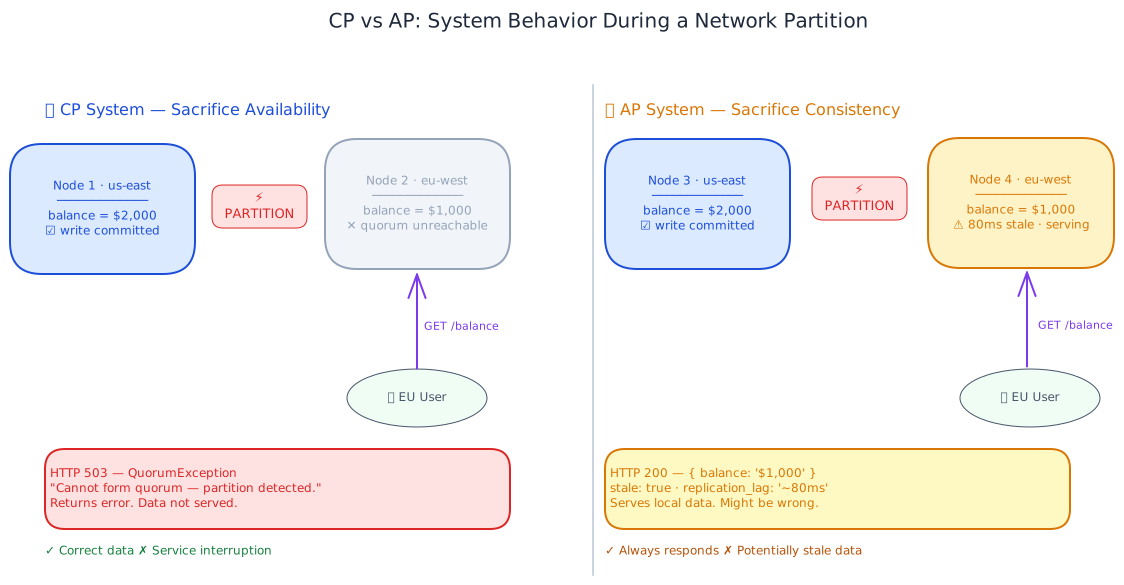
The real-world expression of CAP is two families of distributed systems, each optimized for their side of the partition decision.
CP Systems: Refuse Rather Than Lie
A CP system's contract: "I would rather turn you away than give you wrong information."
ZooKeeper is a common CP-oriented coordination system. It is used for distributed
locking, leader election, and configuration distribution. If its quorum is disrupted,
nodes that cannot confirm the required state may stop serving operations and return an
error such as ConnectionLossException.
The reasoning: a stale leadership result is worse than no result at all. If two nodes both believe they are the leader because a coordination result is stale, both may execute critical sections simultaneously—a race condition that can cause data corruption. ZooKeeper has powered coordination in systems such as Kafka, HBase, and Hadoop. Modern Kubernetes control planes commonly use etcd instead.
When ZooKeeper appears in a design, ask what happens to the dependent service when the coordination quorum is lost. That makes the CP availability trade-off explicit.
When CP is the right call:
- Distributed locks — a stale lock state means two processes enter a critical section simultaneously
- Payment confirmation — a stale "payment succeeded" that hasn't propagated is a silent double-charge
- Inventory decrements at point-of-sale — a stale "1 item in stock" at true zero inventory oversells
- Auth token revocation — a stale "token valid" for 200ms after revocation is a security vulnerability
- Leader election — split-brain leadership causes duplicate task execution and data corruption
AP Systems: Return and Reconcile
An AP-oriented contract is: "return something rather than make the caller wait, then reconcile conflicts later."
Cassandra is often used in AP-oriented deployments. Its consistency level and replication topology determine how many replicas must respond; weaker levels can continue with a local view while stronger levels may block or fail when the required replicas are unreachable.
During a partition, an AP-oriented configuration may accept writes on both sides. When the partition heals, repair and reconciliation mechanisms resolve divergent data using the configured conflict policy, which may include Last Write Wins (LWW).
When AP is the right call:
- User activity feeds and timelines — stale posts are invisible to users; the next refresh catches up
- Recommendation engines — a ~500ms-stale recommendation is indistinguishable from fresh
- View, like, and share counts — approximate counts are acceptable; counters merge cleanly after partition
- Shopping cart contents — slightly stale cart data is annoying but not irreversible
- DNS — responses can be cached (stale) for minutes without meaningful consequences to end users
Pick CP when stale data costs more than downtime. Pick AP when a timeout costs more than stale data. Most production systems use both — the choice is per data type, not per system.
CA is not a meaningful distributed option
CA — Consistency + Availability without Partition Tolerance — describes a system that assumes the communication path never partitions. That can be a useful model for a single-node or tightly bounded deployment, but it is not a durable choice for a system whose replicas communicate over a failure-prone network.
PACELC: The Tradeoff Beyond Partitions
CAP defines behavior during a partition. Systems also make an important normal-path choice between latency and consistency when the network is healthy.
PACELC (proposed by Daniel Abadi, 2012) extends CAP:
Partition → choose A (Availability) or C (Consistency)
Else (normal operation) → choose L (Latency) or C (Consistency)
| System or configuration | Partition behavior (P→A or P→C) | Normal operation (E→L or E→C) |
|---|---|---|
| DynamoDB | Depends on the service's failure model and requested consistency | Eventual or strong reads are selectable; latency and cost differ |
| Cassandra | Depends on consistency level and replica placement | Weaker levels favor latency; stronger levels wait for more replicas |
| HBase | Common deployments favor quorum-backed availability and consistency | Synchronous replication adds coordination latency |
| ZooKeeper | Refuses operations that require quorum when quorum is lost | Coordination reads and writes follow the ZAB protocol |
| Google Spanner | Consensus-backed writes require the needed replicas | External consistency includes replication and, where needed, commit-wait costs |
| MongoDB | Configurable through write and read concern and topology | Read/write concern determines the latency-consistency trade-off |
Understanding PACELC helps answer the normal-path question as well: "What is the system's latency versus consistency trade-off when there is no partition?" A CP/AP label alone does not describe that entire choice.
Trade-offs
| Pros | Cons |
|---|---|
| Forces an explicit design decision — "are stale reads acceptable for this data?" is a question every distributed system should answer intentionally | The CAP framing is binary; real systems are more nuanced — PACELC captures the normal-path latency tradeoff that CAP ignores |
| CP systems give strong correctness guarantees — safety-critical data stays accurate even during failures | CP systems reduce availability — users receive errors during partitions, which is a measurable SLA degradation |
| AP systems maintain service availability — users keep receiving responses even when inter-node connectivity is lost | AP systems require conflict resolution (LWW, vector clocks, CRDTs) — all operationally complex to implement correctly |
| Framework makes database selection principled: pick Cassandra for feeds (AP) and ZooKeeper for locks (CP), not by marketing | CAP doesn't address latency — a system can be CP and still have 200ms writes; PACELC is needed for the full picture |
| Helps identify when a single-node database should stay single-node rather than be distributed unnecessarily | Many "consistency violations" in AP systems can be avoided with session consistency — making the CP/AP binary less relevant at the application layer |
The fundamental tension here is data correctness vs. service availability. Replication can improve failure tolerance while introducing lag and conflict-resolution work. The right answer is often different per data type: AP-style behavior for feeds and analytics where bounded staleness is acceptable, and CP-style behavior for money and locks where stale data has real-world consequences. A useful design exercise is to map each data type to its required consistency and failure behavior.
When to Use It / When to Avoid It
So when does this actually matter? Here's the decision in plain terms.
Choose CP (sacrifice availability during partitions) when:
- Data correctness is more expensive than downtime: financial balances, inventory counts, session tokens, distributed locks
- The downstream action is irreversible: shipping an order, charging a card, sending a legal document, dispatching emergency services
- The data drives regulated or safety-critical decisions, so the system needs an explicitly verified source of truth and an auditable failure policy
- Your system coordinates distributed behavior: leader election, task scheduling, configuration management
Choose AP (sacrifice consistency during partitions) when:
- Stale data is invisible or inconsequential to end users: social feeds, recommendations, personalization, activity logs
- You need multi-region active-active write throughput: global gaming leaderboards, content delivery, analytics ingestion
- Your data naturally handles eventual consistency: counters that merge, sets that union, strings where last-write-wins is correct
- Your consistency requirement can tolerate a bounded staleness window (e.g., "never more than 5 seconds behind")
If a data type does not map cleanly onto either list, specify the unacceptable outcomes, the staleness or downtime budget, and the recovery semantics before choosing a store.
Interview tip: it's a per-table decision, not a per-system decision
Don't say "we'll use an AP database." Say: "The payments table uses quorum reads and writes—CP-style behavior to prevent double-charges. The user timeline table uses eventual consistency because a bounded-stale timeline is acceptable." Many systems use different consistency levels for critical and high-volume data, sometimes within one database cluster.
Real-World Examples
These examples illustrate how the CP-versus-AP decision can be made per data type rather than as a blanket choice for an entire product.
Amazon DynamoDB — AP with tunable consistency by design
Amazon's Dynamo work is a classic example of choosing high availability for workloads that can tolerate stale or conflicting data. DynamoDB exposes different read-consistency options, so a workload can choose eventual or strong reads according to its needs. A shopping cart or recommendation path may accept a different trade-off from a financial ledger. The lesson is that one product can deliberately use different consistency semantics for different data.
Google Spanner — CP at planetary scale
Google Spanner is an example of consensus-backed, globally replicated storage that aims to provide external consistency. It uses TrueTime, an interval API backed by tightly synchronized time sources, to bound clock uncertainty. Commit-wait may be used when needed to preserve external ordering; it is not a universal fixed latency number, and global write latency also depends on replica placement and quorum communication.
Spanner does not escape CAP. If the replicas needed for a commit cannot communicate, the operation may fail or wait rather than commit conflicting state. The example shows how careful time and replication engineering can reduce the normal-path cost of strong consistency, not how to eliminate the partition trade-off.
Netflix on Cassandra — AP with intentional staleness bounds
Netflix has used Cassandra for high-volume activity and recommendation-related workloads, where some staleness can be acceptable. Cassandra's consistency levels can be tuned per operation, allowing stronger settings for data that needs them and weaker settings for latency-sensitive activity data. A multi-region AP-oriented design still has to define conflict resolution, repair, and the maximum acceptable staleness; a CP design would make a different latency and availability trade-off rather than being physically impossible.
How This Shows Up in Interviews
When to bring up CAP proactively
In any design involving multiple nodes storing the same data—replicated databases, distributed caches, or multi-region deployments—state the intended partition behavior early. For example: "The activity feed can use AP-style behavior with a bounded staleness budget, while payment confirmation uses a quorum-backed CP-style service." Tie the choice to the data's correctness and availability requirements.
The most common interview error on this topic is confusing CAP Consistency (linearizability) with ACID Consistency (constraint preservation). They describe different properties.
30-second answer
"CAP says that when replicas are partitioned, a system cannot guarantee both linearizable consistency and availability. Partition tolerance is normally required, so the design chooses CP behavior—reject or delay operations without quorum—or AP behavior— continue serving and reconcile later. I would make that choice per data type and also state the normal-path latency trade-off described by PACELC."
5-minute explanation
Start with a two-node partition: one node accepts a write, the other cannot learn it. If the second node must answer immediately, it may return stale data; if it must stay linearizable, it must reject or wait. That is the CAP trade-off. Then clarify the terms:
- C means linearizability in the CAP model, not ACID constraint checking.
- A means a non-failed node responds, not that the service meets a percentage uptime target.
- P means the system continues to operate despite lost or delayed communication.
- With P required, choose CP or AP behavior for each data type, and define conflict resolution or the quorum/error policy.
Finally, use PACELC to explain the healthy-path choice between lower latency and stronger replica coordination. Give one example—payments or locks as CP-style, feeds or telemetry as AP-style—and state the failure and recovery behavior.
Depth expected at senior/staff level:
- Know the difference between CAP Consistency (linearizability) and ACID Consistency (constraint enforcement) — they are unrelated; confusing them is the most common interview error on this topic
- Identify real partitions that happen in production: BGP flaps, AZ isolation, hot-spot congestion dropping packets, kernel networking bugs
- Choose CP vs AP per data type, not per system — explain which of your design's data is CP-style and which is AP-style
- Know PACELC as the extension of CAP — the consistency-latency tradeoff matters on the normal path too, not only during partitions
- Explain conflict resolution in AP systems (LWW, vector clocks, CRDTs) and when each breaks down
When an interviewer asks "can we avoid CAP with a better network?", address it directly: improving network reliability reduces partition frequency, not partition possibility.
Common follow-up questions and strong answers:
| Interviewer asks | Strong answer |
|---|---|
| "Why can't we just have all three?" | "Partition tolerance isn't optional — every production distributed system experiences network partitions. Given P is required, the choice reduces to C or A during a partition. Two nodes cannot be consistent (agree on the same value) and available (respond immediately) if they can't communicate with each other." |
| "If we use a single-region database, does CAP still apply?" | "Within a single region, partition probability drops dramatically, but partitions still occur — switch failures, NIC brownouts, kernel networking bugs. More importantly, a single-node database isn't distributed, so CAP doesn't technically apply — but the moment you add a replica for high availability, CAP applies immediately. The replica is now a second node and the link between them can partition." |
| "Is Cassandra always AP? Can it be CP?" | "Cassandra's consistency is tunable per query and depends on topology. Weaker levels favor availability and latency; stronger levels require more replicas and can fail when those replicas are unreachable. Describe the chosen consistency level instead of giving the database one fixed CAP label." |
| "What's the difference between CAP and PACELC?" | "CAP describes behavior during partition events. PACELC also asks what the system chooses on the normal path: lower latency with asynchronous replication, or stronger coordination with its added latency. The exact cost depends on placement and implementation." |
| "How does Spanner achieve global strong consistency without violating CAP?" | "Spanner does not violate CAP. It uses consensus-backed replication and can refuse or delay operations when the required replicas are unavailable. TrueTime supplies bounded clock uncertainty for external consistency; it does not remove quorum latency or make the system always available." |
Deep-Dive Questions
Test Your Understanding
Quick Recap
- CAP Theorem states a distributed system can guarantee at most two of: Consistency (linearizability), Availability (always respond), and Partition Tolerance (survive network failures) — never all three simultaneously.
- Partition Tolerance is non-negotiable in any real distributed system — network failures happen at every scale, in every cloud, on every hardware — the true choice is always CP vs AP.
- CP systems (ZooKeeper, HBase, etcd, Spanner) sacrifice availability during partitions — they return errors rather than serve data that might be stale, because in their domains (locks, coordination, financial records), wrong data is worse than no data.
- AP systems (Cassandra, DynamoDB, CouchDB, Riak) sacrifice consistency during partitions — they return their local view of data and converge after the partition heals via LWW or vector clock conflict resolution.
- CAP Consistency (linearizability) is completely unrelated to ACID Consistency (constraint enforcement) — confusing the two is the most common and most costly interview error on distributed systems topics.
- PACELC extends CAP: even without a partition, every distributed replication strategy trades latency for consistency on the normal path — synchronous quorum writes are consistent but slow; async replication is fast but stale.
- The right answer is almost always per-data-type: CP for money, locks, auth tokens, and safety-critical data; AP for feeds, counts, recommendations, and telemetry where bounded staleness is acceptable.
Related Concepts
- Consistency Models — CAP Consistency is one point on a full spectrum. Eventual, monotonic, session, causal, and linearizable consistency are the complete model — reading this article next shows how to select the right model per data type rather than defaulting to the strongest or weakest.
- Replication — The mechanical reality behind CP vs AP choices: how primary-replica setups implement replication lag, semi-sync replication, quorum writes, and WAL-based consistency — the actual system behavior that embodies the CAP tradeoff.
- Databases — SQL vs NoSQL framing maps directly onto CAP choices: most NoSQL databases explicitly chose AP for horizontal scale; SQL databases historically chose either CA (single-node) or CP (distributed, strict quorum). Understanding CAP makes database selection principled.
- Sharding — Sharding distributes writes horizontally, but each shard is itself a distributed system making its own CAP choice. Understanding CAP per-shard is necessary for designing correct sharded architectures where cross-shard transactions need explicit consistency models.
- Microservices — In a microservices architecture, each service's data store makes its own CAP choice independently. Cross-service eventual consistency (saga pattern) emerges from composing AP-style services — CAP understanding is prerequisite to understanding saga correctness and failure compensation.
Related Articles
Learn what consistency models guarantee, which model fits your data, and how to avoid the silent data corruption that happens when you choose wrong.
Master how database replication scales reads, survives failures, and trades off consistency for availability. Learn replica lag, read stale data purposefully, and why your most critical business logic must run on the primary.
Learn how databases organize data for fast retrieval, which storage engine to choose for your workload, and how ACID transactions keep concurrent writes correct at scale.
Learn how data partitioning splits rows across nodes for horizontal scalability, when to pick range vs hash vs directory-based strategies, and how to handle hotspots and rebalancing.