API Gateway
Learn what an API Gateway is, how it works, its trade-offs, and how to explain it in a system design interview.
TL;DR
- An API Gateway is a common entry point for client traffic that sits in front of backend services and routes requests to the right upstream.
- It centralises cross-cutting concerns — authentication, rate limiting, routing, and logging — so each service doesn't have to implement them separately.
- The main trade-off: it simplifies client logic dramatically, but it becomes a single point of failure and a potential performance bottleneck if not made highly available.
- Use it when several services need a shared north-south policy boundary; it is not automatically useful for a monolith or internal service-to-service traffic.
The Problem It Solves
Every time you open a mobile app and see data from several backend sources load in one shot — your profile, your feed, your notifications, your recommendations — an API Gateway may be part of the path. Clients do not need to know whether the backend is a monolith, a set of services, or a mix of both.
Picture a mobile app that needs to show a user's home screen. To render it, the client must call the User Service (for profile data), the Feed Service (for posts), and the Notification Service (for the badge count). That's three round trips.
Now multiply: three different auth systems to satisfy, three different error response formats to parse, and three different rate limiters to stay under. Add a web client and a third-party integration and you have nine separate connections to manage — each with its own quirks. The client complexity grows quickly, but the architectural boundary that can consolidate those concerns is often missing.
The scaling problem
When you have 10 microservices and 3 client types, you're managing 30 potential connection contracts. Adding one new service means updating every client. That complexity compounds fast.
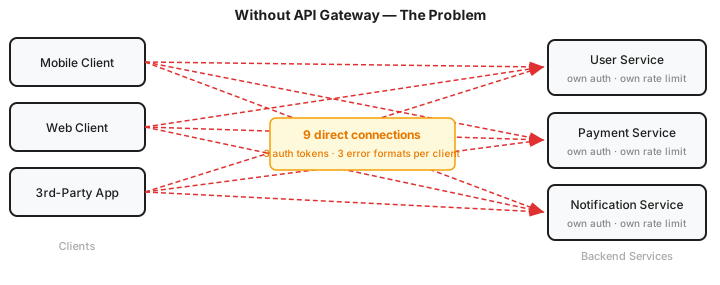
A common way to reduce this coupling is an API Gateway: one front door for client traffic, with an explicit contract and shared edge policies.
What Is It?
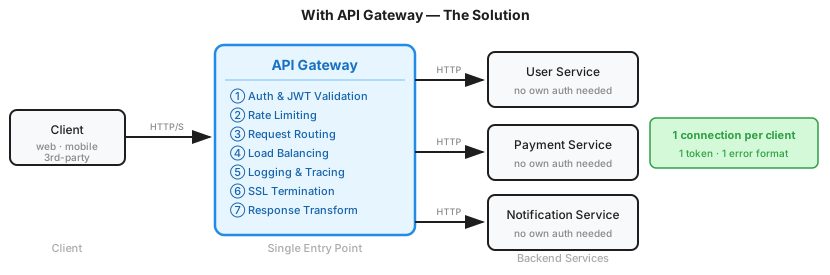
An API Gateway is a reverse proxy that acts as a common entry point for client requests. It can route them to the correct backend service and handle shared concerns such as authentication, rate limiting, logging, TLS termination, and protocol translation.
Analogy: Think of it like a customs checkpoint at an international border. Every vehicle passes through exactly one booth — you don't drive straight to the warehouse, the freight office, or the inspection bay.
The officer checks your documents (auth), confirms you haven't exceeded import limits (rate limiting), and directs you to the correct lane for your cargo type (routing). The checkpoint handles shared rules so the facilities behind it can stay focused on their actual work.
In a design discussion, a concise description is: "The API Gateway handles client-facing routing, authentication, and rate limiting." Then explain the gateway's availability and failure behavior if those matter to the design.
Don't overthink it
An API Gateway is usually narrow in scope. It routes, checks policy, and may translate protocols or representations. The value is in giving shared client-facing plumbing one owner; business rules should remain in the services that own them.
How It Works
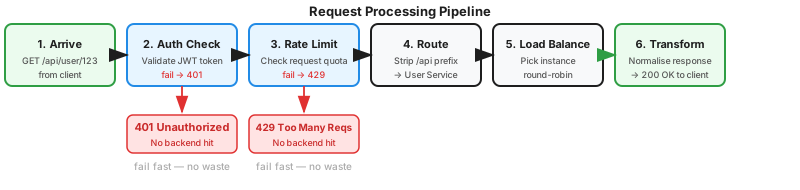
When a client sends GET /api/products/SKU-789, this is one possible request pipeline.
The exact order and enabled stages depend on the gateway and the system's security
requirements.
-
Request arrives — The gateway receives
GET /api/products/SKU-789from the client. Before anything else fires, it performs a basic structural check: is the URL path valid? Are the required headers present? Does the body (if any) conform to the declaredContent-Type? A malformed payload or missing required field gets a400 Bad Requestright here — no auth check, no backend hit. This is cheap to run and keeps garbage out of the rest of the pipeline. -
Auth Check — Validates the JWT token in the
Authorizationheader. Invalid or missing? Return401 Unauthorizedimmediately. No backend service is ever touched. This is one of the biggest wins — unauthenticated traffic is eliminated at the edge. -
Rate Limiting — Checks the client's request count against the quota (e.g., 1,000 requests/minute, as an illustrative quota). Over the limit? Return
429 Too Many Requests. Again, no backend hit. -
Routing — Strips the
/apiprefix and maps the path to the correct service./api/products/SKU-789becomes a request to the Catalog Service. Routing is driven by a config table that maps paths, HTTP methods, and headers to upstream services:routes: - path: /products/* service: catalog-service port: 9001 - path: /cart/* service: cart-service port: 9002 - path: /checkout/* service: checkout-service port: 9003 -
Load Balancing — Picks one instance of the Catalog Service (e.g., round-robin across three running instances) to distribute load evenly.
-
Response Transformation — Translates the backend's response into whatever format the client expects. When backend services communicate internally over gRPC (for efficiency), the gateway can handle the protocol conversion so clients can continue to see JSON over HTTP:
// Client: GET /products/SKU-789  (HTTP/1.1 + JSON)

// Gateway translated to an internal gRPC call:
catalogService.getProduct({ sku: "SKU-789" })

// Gateway returned to client (JSON over HTTP):
{ "sku": "SKU-789", "name": "Wireless Headphones", "price": 79.99 }
Clients never need to know what protocol the backend uses — the gateway abstracts that boundary entirely.
-
Cache (optional) — If the response is non-user-specific and deterministic (the same request always returns the same result), the gateway can store it before returning to the client. The next identical request is served from cache — no backend service is touched at all. Common strategies include full-response caching with a TTL or partial caching for response fragments that rarely change. A distributed cache such as Redis is one possible backing store.
Why steps 2 and 3 matter so much
Because auth and rate limiting can happen at the gateway, many malicious or misconfigured requests can be dropped before they consume backend compute. At scale, that can remove substantial unwanted traffic from downstream services.
The cheap rejections come first — auth at step 2, rate limiting at step 3. Your backend services never see garbage traffic.
Key Components
Each of these is either a built-in module in managed gateways or a plugin in self-hosted ones:
| Component | What It Does |
|---|---|
| Router | Maps incoming paths/methods to the correct upstream service. Often uses a config file or service registry. |
| Auth Handler | Validates credentials (JWT, API key, OAuth token) and optionally enriches the request with user context. |
| Rate Limiter | Tracks request counts per client (or IP, or API key) and enforces quotas. Usually backed by Redis. |
| Load Balancer | Distributes requests across healthy instances of the target service. Often round-robin or least-connections. |
| Circuit Breaker | Stops sending requests to a failing downstream service, returning a fallback response instead (see Circuit Breaker pattern). |
| Request/Response Transformer | Modifies headers, rewrites paths, translates protocols (REST ↔ gRPC), or reshapes payloads. |
| Logger / Tracer | Emits a structured log and a distributed trace span for every request — the single best place for system-wide observability. |
| TLS Terminator | Handles TLS at the edge. Depending on the trust boundary, the gateway may re-encrypt traffic to the upstream instead of using plain HTTP internally. |
Types of API Gateways
Not all gateways are the same. The useful distinction is the boundary they serve and how much control the team wants to operate:
| Type | Examples | Best For |
|---|---|---|
| Managed cloud gateway | AWS API Gateway, Azure API Management, GCP Apigee | Public-facing APIs, serverless backends, teams that want zero ops overhead |
| Self-hosted open-source | Kong, KrakenD, Traefik, NGINX Plus | Fine-grained control, on-prem deployments, cost-sensitive at scale |
| BFF (Backend for Frontend) | Custom Next.js API routes, GraphQL gateway | Client-specific aggregation — one gateway per surface (mobile BFF, web BFF) |
BFF pattern
A Backend for Frontend gateway is a specialised variant: instead of one universal gateway, each client type gets its own thin gateway that aggregates and reshapes data specifically for that client's needs. The pattern is especially useful when mobile, web, and partner clients need materially different response shapes.
Pick a category, justify it in a sentence, and connect the choice to the system's operational constraints. The important trade-off is control and customization versus operational effort and provider coupling.
Popular API Gateways
Managed Cloud Services
Fully managed options integrate tightly with their cloud ecosystem and reduce gateway operations. They can introduce provider coupling, and pricing and feature limits should be checked against expected traffic and requirements.
AWS API Gateway
- Native integration with Lambda, ECS, and IAM
- Supports REST, HTTP, and WebSocket APIs out of the box
- Built-in request throttling, API key management, and CloudWatch metrics
- A common choice for serverless architectures on AWS
Azure API Management
- Policy engine lets you rewrite headers, validate request schemas, and mock responses entirely in config — no service code changes needed
- First-class support for enterprise identity protocols: OAuth 2.0, OIDC, and Active Directory integration out of the box
- Includes a hosted developer portal where consumers can browse docs, test endpoints, and generate API keys without a separate tool
Google Cloud Endpoints / Apigee
- Deep integration with GCP services and Cloud Run
- First-class gRPC support alongside REST
- Apigee (Google's enterprise tier) adds advanced analytics and monetisation features
Open-Source / Self-Hosted
These options provide more control and can reduce provider coupling. The team owns the deployment, upgrades, scaling, and operational burden.
Kong
- Plugin-first architecture: nearly every capability (auth, rate limiting, request transformation, tracing) is a composable plugin rather than baked-in code
- Runs as a standalone gateway, a Kubernetes ingress controller, or a service mesh sidecar — adaptable to most deployment topologies
- Declarative config via
deck(GitOps-friendly) or a REST Admin API
KrakenD
- Stateless by design — no database dependency, no persistence layer
- Extremely high throughput; favoured for latency-sensitive workloads
- Declarative JSON/YAML config, no runtime scripting
Traefik
- Kubernetes-native with automatic service discovery via labels
- Automatic TLS certificate provisioning via Let's Encrypt
- Popular choice when you're already running on Kubernetes
In an interview, compare only the options relevant to the stated constraints. Pick the one that matches the cloud environment or operational model and state the reason.
What to say in an interview
You don't need to memorise every option. A concise answer names the deployment model, the relevant integration, and the cost: "I would use the managed gateway that matches our cloud environment if its quotas and pricing fit; otherwise I would operate a self-hosted gateway for the required control."
Scaling an API Gateway
Horizontal Scaling
API Gateways are often designed to be stateless: session state and distributed rate limit counters live in external systems when those features need shared state. This makes horizontal scaling straightforward, but the external dependencies and control plane still need their own availability design.
There are actually two separate load balancing concerns at play:
| Layer | Who handles it | Example |
|---|---|---|
| Client → Gateway LB | A dedicated cloud load balancer in front of the gateway cluster | AWS ELB, Google Cloud LB, NGINX |
| Gateway → Service LB | The gateway itself, picking which instance of the target service to call | Round-robin, least-connections built into the gateway |
In a high-level diagram, one box can represent both layers. In a production design, keep the two responsibilities clear so health checks, TLS policy, and upstream routing can be tuned independently.
Interview shortcut: draw one box
In a system design interview, a single box labelled "API Gateway / Load Balancer" is acceptable when the distinction does not affect the design. Call out the separate layers when their failure modes or scaling limits matter.
Global Distribution
For large-scale systems with users spread across multiple regions, you can push gateway instances closer to users — the same idea as a CDN edge node, but for API traffic:
- Regional deployments — Run gateway clusters in each geographic region (e.g., us-east, eu-west, ap-southeast).
- GeoDNS routing — Resolve the API domain to the nearest regional gateway based on the client's location. Reduces round-trip latency before the request even reaches your backend.
- Config synchronisation — Routing rules, rate limit policies, and auth config must stay consistent across all regional instances. Centralised config management (e.g., a control plane like Kong's) handles this.
Use regional gateway deployments when latency, regional isolation, data residency, or regional failover justifies the configuration and consistency work. A single-region deployment is simpler when those requirements are absent.
Trade-offs
| Pros | Cons |
|---|---|
| Centralises cross-cutting concerns → services stay lean | Single point of failure — must be made highly available |
| Simplifies client code → one auth token, one error format | Adds one network hop → increases latency by an amount that depends on placement and per-request work |
| Enables protocol translation (REST → gRPC, HTTP/1 → HTTP/2) | Can become a bottleneck at high request volume or when per-request work is expensive |
| One place for observability: logs, metrics, traces | Adds operational complexity — another system to deploy and tune |
| Faster security response → block bad actors at the edge | Gateway config can become a sprawling blob of routing rules |
The fundamental tension here is simplicity vs. resilience. The gateway simplifies client contracts, but it concentrates client traffic and policy in one component.
The common availability mistake is to add a gateway for routing and then leave it as a single instance. A usual mitigation is multiple stateless instances behind a load balancer, with health checks, capacity headroom, and a tested failure policy.
The gateway bottleneck trap
When a gateway handles auth, rate limiting, and heavy response transformation for millions of requests per second, it can become the system's CPU bottleneck. Profile before adding expensive per-request transformations.
A single gateway instance creates avoidable availability risk. The right redundancy level depends on the service objective and failure domains, but it should be tested as part of the production design.
When to Use It / When to Avoid It
An API Gateway makes sense when it solves a real client-facing boundary or policy problem; it is overkill when it merely adds a hop without removing duplicated work.
Use an API Gateway when:
- Several backend services need to be exposed through a consistent client-facing contract.
- You have multiple client types (mobile, web, third-party) with different data needs.
- You need centralised auth, rate limiting, or observability without duplicating logic in every service.
- You're exposing a public API and need developer portal features (API keys, docs, versioning).
Avoid an API Gateway when:
- You have a monolith — it adds latency with zero benefit.
- You're dealing only with internal service-to-service traffic — a service mesh (Istio, Linkerd) or direct service discovery may be a better fit; a gateway is primarily a north-south boundary.
- Your team can't support the operational overhead of a distributed gateway cluster.
- You have a single backend with one client type — a reverse proxy like NGINX is sufficient.
Several services and multiple client types are a strong signal to evaluate one. One backend and one client may need only a reverse proxy, depending on the policies required.
Gateway vs. Service Mesh
A common interview trap: confusing gateways and service meshes. A gateway handles client-to-service (north-south) traffic. A service mesh handles service-to-service (east-west) traffic. You often use both together — not one instead of the other.
Real-World Examples
Netflix has used purpose-built gateway software such as Zuul and Zuul 2 for authentication, dynamic routing, and device-aware traffic handling. It is a useful example of why a large organization with many client surfaces may choose to own more of the gateway stack, although the same choice is not automatically appropriate for a smaller team.
Uber has described gateway and aggregation layers that fan out a single rider-app request to multiple microservices (mapping, pricing, driver-matching) and aggregate their responses before returning them — a classic request aggregation use case.
AWS API Gateway + Lambda is a common serverless pattern: the gateway can handle HTTP concerns, throttling, and authentication while the Lambda function focuses on business logic. The exact split depends on the chosen integrations and policies.
Any one of these examples can ground an interview answer, provided the example is tied to the design constraint rather than used as a generic appeal to authority.
How This Shows Up in Interviews
The API Gateway is often a supporting building block rather than the central feature of the design. Name it early, explain its responsibilities, and spend more time on the parts that determine correctness, scale, and failure behavior.
30-second answer
"I would put an API Gateway at the client-facing boundary to route requests to the appropriate service and centralize policies such as authentication, rate limiting, TLS, and observability. I would keep business logic in the services, run the gateway with redundant stateless instances, and use a service mesh or direct discovery for service-to-service traffic."
5-minute explanation
Start with the traffic boundary and the request path: the gateway receives a client request, validates the request and credentials, applies a quota, routes to a healthy upstream, and returns or transforms the response. Then state the important choices:
- Contract and routing: path or header versioning, upstream discovery, and whether a BFF is needed for client-specific aggregation.
- Protection: timeouts, bounded retries, circuit breaking, request-size limits, and a rate-limit store that remains available when the gateway is scaled out.
- Availability: multiple instances across failure domains, a load balancer, configuration rollout and rollback, and a clear policy for gateway or dependency failure.
- Performance and privacy: avoid expensive transformations on the hot path, cache only responses that are safe to share, and decide whether TLS is re-encrypted to the upstream.
Close by distinguishing north-south gateway traffic from east-west service-mesh traffic and by naming the trade-off: the gateway reduces duplicated client-facing plumbing but adds a hop and concentrates operational risk.
When to bring it up
In a system design question involving multiple services and external clients, draw an API Gateway early when it addresses the client-to-service communication or policy layer. Do not add it automatically if the requirements do not need that boundary.
Don't get bogged down here
The API Gateway need not take over the whole discussion. A common mistake is spending five minutes listing every middleware feature it could have. Instead, say: "I'll add an API Gateway to handle routing and basic middleware like auth and rate limiting" — and move on. Spending too much time here is far more likely to hurt you than not enough.
Depth expected at senior/staff level:
Don't just draw a box labelled "API Gateway." Talk through what it's doing:
- Which auth strategy? (JWT? OAuth2 with an introspection endpoint? mTLS for machine-to-machine?)
- What's your rate limiting strategy? Per-user or per-IP? What backing store? (Redis for distributed state.)
- How do you make the gateway itself highly available? (Multiple instances + a cloud load balancer in front. Gateway instances are stateless — sessions are in Redis, not memory.)
Common follow-up questions and strong answers:
| Interviewer asks | Strong answer |
|---|---|
| "What if the gateway goes down?" | "Run multiple gateway instances behind a load balancer, with health checks and capacity headroom. Keep any shared state in a highly available external store when the gateway feature needs it." |
| "How do you handle versioning?" | "Path-based (/v1/, /v2/) or header-based (API-Version: 2). The gateway routes by version prefix; old and new services co-exist." |
| "Would you use a gateway for internal traffic?" | "No — that's a service mesh. Gateway is north-south (client → service). Mesh is east-west (service → service). I'd use both." |
| "How do you avoid the gateway bottleneck?" | "Horizontal scaling + profile the gateway. Offload SSL to a CDN/L4 LB. Push heavy transforms to the services themselves if the gateway becomes the CPU bottleneck." |
These answers cover the main concerns when gateway specifics are relevant: availability, traffic direction, version routing, and per-request cost.
Offload expensive gateway work carefully
For high-volume APIs, point out which work can be offloaded or made local. A signed token can let a service validate a request without a per-request call to an auth service, but bypassing gateway controls requires an explicit threat model, consistent policy, and service-side validation. Do not remove authentication or authorization checks merely to reduce gateway CPU.
Deep-Dive Questions
Test Your Understanding
Quick Recap
- An API Gateway is a reverse proxy — the single entry point for all client-to-service communication.
- It centralises auth, rate limiting, routing, load balancing, and logging so services stay focused on business logic.
- Auth and rate limiting happen before any backend service is touched — this is the "fail fast at the edge" principle.
- It introduces a single point of failure; mitigate with multiple stateless instances behind a load balancer.
- Types: managed cloud (AWS API Gateway), self-hosted (Kong, KrakenD), and BFF (one per client surface).
- Use it for north-south (client → service) traffic; use a service mesh for east-west (service → service) traffic.
- In interviews: draw it early, explain what it's doing, and proactively address high availability and the bottleneck risk.
Related Concepts
- Load Balancing — The gateway often delegates load balancing decisions to a separate LB layer or uses an embedded algorithm.
- Rate Limiting — One of the most important gateway responsibilities; understanding token buckets and sliding windows helps you design the rate limiter inside the gateway.
- Service Mesh — The complementary pattern for east-west traffic that a gateway doesn't handle.
- Microservices — Gateways provide the most value in microservice architectures; understand why before designing one.
- Circuit Breaker — A pattern commonly implemented at the gateway layer to protect downstream services from cascading failures.
Related Articles
Learn how load balancers distribute traffic across servers, which algorithms to choose, and how to design a highly-available app tier in any system design interview.
Learn how rate limiting caps request throughput per client, which algorithm to choose for your traffic pattern, and how to enforce limits correctly in a distributed system.
Learn how a service mesh eliminates duplicated networking code across microservices, enforces zero-trust mTLS by default, and gives you end-to-end observability without touching your application code.
Learn how microservices decompose monolithic applications into independently deployable services, when the operational overhead is worth it, and how to manage the distributed-systems failure modes that follow.